

Okay so recently I posted a demo of how I setup realtime editing in Blender, showing as I make any changes to my level in Blender, it updates instantaneously in my game engine. And since so many people liked the concept and are interested in being able to use it, I’m writing this blog post to detail all the steps that went into creating it.
This article is divided into two parts. In the first part I talk about the advantages of this approach and in the second part, I walk you through how you create something like this, with a special surprise at the end!
Foreword
I have a fair amount of experience working with publicly available game engine and modding tools, and I’ve noticed something critical: The quality of your level editor directly determines the quality of your game. The better your development tools are and the faster your iteration cycles are, the higher the quality of your game.
The standard procedure for making levels hasn’t changed in years. You create models in a 3D authoring tool like Maya or Blender, import them into your game engine, adjust materials, and scale, then place them using the engine’s basic 3D editing tools. This is how it works in Unity, Unreal Engine, Source engine, and most other game engines. It’s familiar, but it’s also limiting.
The problem is that 3D authoring tools like Maya and Blender have sophisticated, fine-tuned controls for 3D content creation and manipulation, while game engine editors only offer a set of features. It is also extremely time consuming to create even a simple 3D editor, let alone a complex one, which has all the bells and whistles that artists and level designers need. All that time and effort that can be spent on other parts of your game.
But what if you actually didn’t have to create a level editor? A tool like Blender can be repurposed to create great levels and it will give a huge head start in development process.
And the best part is that it’s already proven! People know how to use it. When you hire artists or level designers, they’re likely already familiar with Blender. If not, there are tons of learning resources available. Compare this to a custom editor where you’d have to spend the time to write documentation and train your artists on how to use them. There are additional advantages such as when your engine crashes, your editor will be fine and you don’t have to worry about losing progress working on a level.
The biggest drawback is that the Blender editor preview doesn’t show your scene with the final lighting through your engine’s rendering pipeline, but if you have a hot-reloading setup that let’s you see the changes in realtime, this drawback is effectively eliminated!
I’m not the first person with this idea and there are other game developers, both in the indie and AAA scene that do a similar thing. Lucas Pope, creator of "Return of the Obra Dinn" follows a similar workflow with him using Maya as his level editor.1 Also the folks from Santa Monica who made the God of War games, follow a similar workflow in Maya.2
Why Blender?
I had prior experience in Blender, making models, and animations, so I knew my way around it, and also over the years I grew to appreciate the feature set and how it kept improving, while performing much better than Maya or 3ds Max. Also with Blender being an open source C++ project, it meant that I would be able to modify it to suit my needs by directly changing the code.
But ultimately, you can achieve similar results from other applications than Blender.
Why is this blog post so long?
Right, since Blender does not expose a C api to write extensions, this meant that to make the required changes, I had to dive deep into Blender source code, and I couldn’t find any learning material and the few bits of information was sparsely scattered over various chat rooms and forum posts.
So this blog post is an amalgamation of knowledge that I discovered through the process of making this exporter, and I think its valuable for people who want to create a similar thing to have the knowledge accessible in a somewhat organized format.
Also I hope that this project demonstrates how much cool plugins Blender users are missing out on, by the fact there is no C api for developers to write crazy good plugins that can be distributed to users through .dll and shared library files.
Getting technical
With all of that out of the way, let’s get into the technical nitty gritty. The rest of this blog will follow like a tutorial with dos and don’ts that I’ve learned in the process of making my live editing setup.
This will save you hours of trial and error, and research on how to get things going. With that said, most of my knowledge comes through trial and error and less an engineering approach. So if you notice things can be improved or there are much better ways of doing them, I would love to hear from you.
Outline
This is an overview of the steps that I’ll cover in this article.
Compiling Blender
Debugger setup
Hello exporter
Covering the many parts of the exporter
Optimizations
Compiling Blender
This part is relatively straight forward, in the sense that "it just worked™" and I didn’t have to do anything crazy to make it compile which is more than what I can say about most open source projects.
The important part is to choose a stable Blender version with the idea that you stick with that version for as long as possible. Blender internals change a lot in version updates so porting the exporter to newer versions always has the possibility of coming with extra surprises.
With that said, I chose Blender 4.5 which at the time of making the exporter was the latest stable build. Previously, when I had a python only version of the exporter, I was using Blender 4.0 and never bothered upgrading since it meant that I’d have to update the python code.
I assume you have your MSVC compiler toolchain and development environment already setup.
Also spoiler! You’ll need a lot of disk space for this. The source code and the binaries roughly take 50 GB of space on my machine.
git clone https://projects.blender.org/blender/blender.git
git checkout blender-v4.5-release
Before you can even begin compiling you have to run the following command in the blender folder:
make.bat updateIt will download a whole lot of stuff which apparently Blender depends on.
Then also from the blender folder run the following commands which create two folders for the debug and optimized builds.
make.bat debug developer ninja
make.bat ninja
You can apparently use other build systems as well, but I found ninja to be the fastest and most hassle free.
After those commands have run successfully, you should have two new folders next to the blender source code repo:
build_windows_x64_vc17_Debug
build_windows_x64_vc17_Release
You can now enter the _Debug folder and run the ninja command to compile and produce Blender binaries.
ninjaThis process will take a minute… or two… or three… or thirty minutes. The compile times are unfortunately abysmal especially when compiling with optimizations enabled in release mode. This part is unfortunately terrible.
After it’s done, it will produce binaries in the /bin folder. If you want to produce release binaries, run the same ninja command in the Release folder.
It’s worth pointing out that subsequent builds will take much less time, but they still feel like an eternity.
Tangent:
Since the linking times are so atrocious, I tried to use alternative linkers instead of the microsoft linker to hopefully speed up the compilation process, namely RADLink and mold. I did so by overriding the linker executable path in the cmake script, but unfortunately, both RADLink and mold only accept their own bespoke command line arguments and are incompatible with the microsoft linker flags.It would have been great if both linkers can accept the microsoft linker flags and automatically convert it to their accepted format.
I quickly gave up on using a custom linker, as it would’ve been totally infeasible for me to manually convert all of the custom linker flags in the blender cmake scripts.
Reducing the barrier to entry to a drop in replacement will benefit a lot of people, since I can safely assume many C++ codebases suffer from atrociously long compile and link times.
Debugger setup
Unfortunately, debugging blender is only supported by the visual studio debugger. I could not make RAD Debugger or RemedyBG to work with it. This is really unfortunate because Visual Studio is nerve-wrackingly slow!
The reason is that the way msvc stores the debug information in the blender build setup makes both RadBG and RemedyBG unable to find the debug symbols.
With the help of a blender developer, I actually got it to work for one build, but the chat logs are gone and now I cannot figure out how I did it in the first place. It involved editing the cmake script to remove the fastlink flags. This unfortunately destroyed the compile times even more, but after a clean recompile, I was able to step through the code in RadDbg. However, upon recompilation, RadDbg would again fail to find the symbols. So I gave up on trying to make it work. Chances are, if you know your way around cmake you can get it to work. If you do, please share it!
With that said, you can launch blender from the visual studio debugger by calling devenv.exe on blender.exe in the bin folder.
devenv.exe blenderHello Exporter
Here is the outline of the process to have the equivalent of hello word of addons:
Adding a new cmake script to include our new code in the build step
Writing the placeholder code
Registering our exporter with Blender
Calling our exporter from within Blender
Step 1:
First, create a folder in the blender\source\blender\io\ folder that will contain all of the exporter code. I chose the folder name rift. You’ll also find other exporters in the io folder such as the fbx and obj exporter.
In the rift folder, create a CMakeLists.txt file which contains the build script, and a rift_exporter.cc file which will provide shelter for the C code.
Fill the cmake file with the following content:
Chances are some of the stuff there is not needed, but I had them at one point or the other while testing.
set(INC
  .
  ../../../intern/guardedalloc
  ../../blenkernel
  ../../blenlib
  ../../bmesh
  ../../depsgraph
  ../../makesdna
  ../../makesrna
  ../../windowmanager
)

set(INC_SYS
)

set(SRC
  rift_exporter.cc # exporter source file
)

set(LIB
  PRIVATE bf::blenlib
  PRIVATE bf::depsgraph
  PRIVATE bf::dna
  PRIVATE bf::intern::guardedalloc
  bf_windowmanager
  bf_editor_space_topbar
  bf_bmesh
  bf_imbuf
)

blender_add_lib(bf_io_rift "${SRC}" "${INC}" "${INC_SYS}" "${LIB}")
You also have to update the CMakeLists.txt file in the blender\source\blender\io, and add the following line to it for cmake to actually use our new script file:
add_subdirectory(rift) # folder nameAnd feel free to replace this name with your preferred name.
Finally, you have to update the cmake file in blender\source\windowmanager and add the following line to the set(LIB … section:
bf_io_riftThis will be used later when the addon is registered.
Step 2: Wow, time to write some actual code
Tip:
I recommend using an editor with LSP support (at least in the beginning) to get error information faster, and being able to jump to definitions. I normally recommend against them and personally use a very minimal and simple editor, but the long and annoying compile times, bring a value proposition to LSPs since they provide error information much faster as you are typing. Visual Studio worked out of the box.Otherwise the debugger is your best friend and always launch the executable through the debugger.
The following piece of code is the basic setup for an exporter than can be invoked from within Blender:
//
// Blender headers, you’ll need all of them by the end of the article.
// Just include them all :)
//

#include "BLI_path_utils.hh"
#include "BLI_fileops.h"
#include "BLI_math_vector.h"
#include "BLI_math_matrix.h"
#include "BLI_math_rotation.h"
#include "BLI_string.h"
#include "BLI_listbase.h"
#include "BLI_map.hh"
#include "BLI_bounds_types.hh"
#include "BLI_bounds.hh"
#include "BLI_time.h"

#include "BKE_context.hh"
#include "BKE_main.hh"
#include "BKE_scene.hh"
#include "BKE_object.hh"
#include "BKE_mesh.hh"
#include "BKE_material.hh"
#include "BKE_image.hh"
#include "BKE_node.hh"
#include "BKE_customdata.hh"
#include "BKE_idprop.hh"
#include "BKE_lib_id.hh"
#include "BKE_main.hh"
#include "BKE_attribute.hh"
#include "BKE_deform.hh"
#include "BKE_mesh_tangent.hh"
#include "BKE_attribute.hh"
#include "BKE_node_legacy_types.hh"
#include "BKE_image_save.hh"
#include "BKE_image_format.hh"
#include "BKE_editmesh.hh"
#include "BKE_modifier.hh"
#include "BKE_mesh_wrapper.hh"

#include "RNA_access.hh"
#include "RNA_define.hh"

#include "WM_api.hh"
#include "WM_types.hh"

#include "DEG_depsgraph.hh"
#include "DEG_depsgraph_query.hh"

#include "DNA_object_types.h"
#include "DNA_meshdata_types.h"
#include "DNA_modifier_types.h"
#include "DNA_mesh_types.h"
#include "DNA_material_types.h"
#include "DNA_scene_types.h"
#include "DNA_image_types.h"

#include "bmesh.hh"
#include "bmesh_tools.hh"

using namespace blender;

/////////////////////////////////////////////////////////////////

//
// Actual exporter code/logic.
//
static void rift_exporter_main (bContext *C, const char *filepath) {

    printf("We are in! Filepath: %s \n", filepath);
}

//
// Exporter entry point, triggered from python
//
static wmOperatorStatus rift_export_exec (bContext *C, wmOperator *op) {

    char filepath[FILE_MAX];
    RNA_string_get(op->ptr, "filepath", filepath);

    rift_exporter_main(C, filepath);

    return OPERATOR_FINISHED;
}

//
// Adds the ability for the exporter filepath to be selected from the blender file picker menu
//
static wmOperatorStatus rift_export_invoke (bContext *C, wmOperator *op, const wmEvent *) {

    WM_event_add_fileselect(C, op);
    return OPERATOR_RUNNING_MODAL;
}

//
// Init function, registered on startup
//
extern "C" void EXPORT_SCENE_OT_rift (wmOperatorType *ot) {

    ot->name = "Export to Rift";
    ot->idname = "EXPORT_SCENE_OT_rift";
    ot->description = "Export scene to .rift format";

    ot->invoke = rift_export_invoke;
    ot->exec = rift_export_exec;
    ot->poll = WM_operator_winactive;
    ot->flag = OPTYPE_REGISTER | OPTYPE_UNDO;

    // Add a filepath argument to the exporter function.
    // You can add more arguments as you wish!
    RNA_def_string_file_path(ot->srna, "filepath", nullptr, FILE_MAX, "File Path", "Destination .rift file");
}
Step 3: Registering the addon
In the source/blender/windowmanager/intern/wm_operators.cc file, you need to add two things:
At the top of the file add the same function prototype from the exporter:
extern “C” void EXPORT_SCENE_OT_rift (wmOperatorType *ot);And in the wm_operatortypes_register function add the following line somewhere in there:
WM_operatortype_append(EXPORT_SCENE_OT_rift);Step 4:
To invoke the exporter, you need to call it from python, which sucks, but endure we must. However, you don’t need to write the python plugin for it just yet!
You can call the exporter from Blender’s built-in python command line tool, accessible from the Scripting tab, by calling:
bpy.ops.export_scene.rift(filepath="test")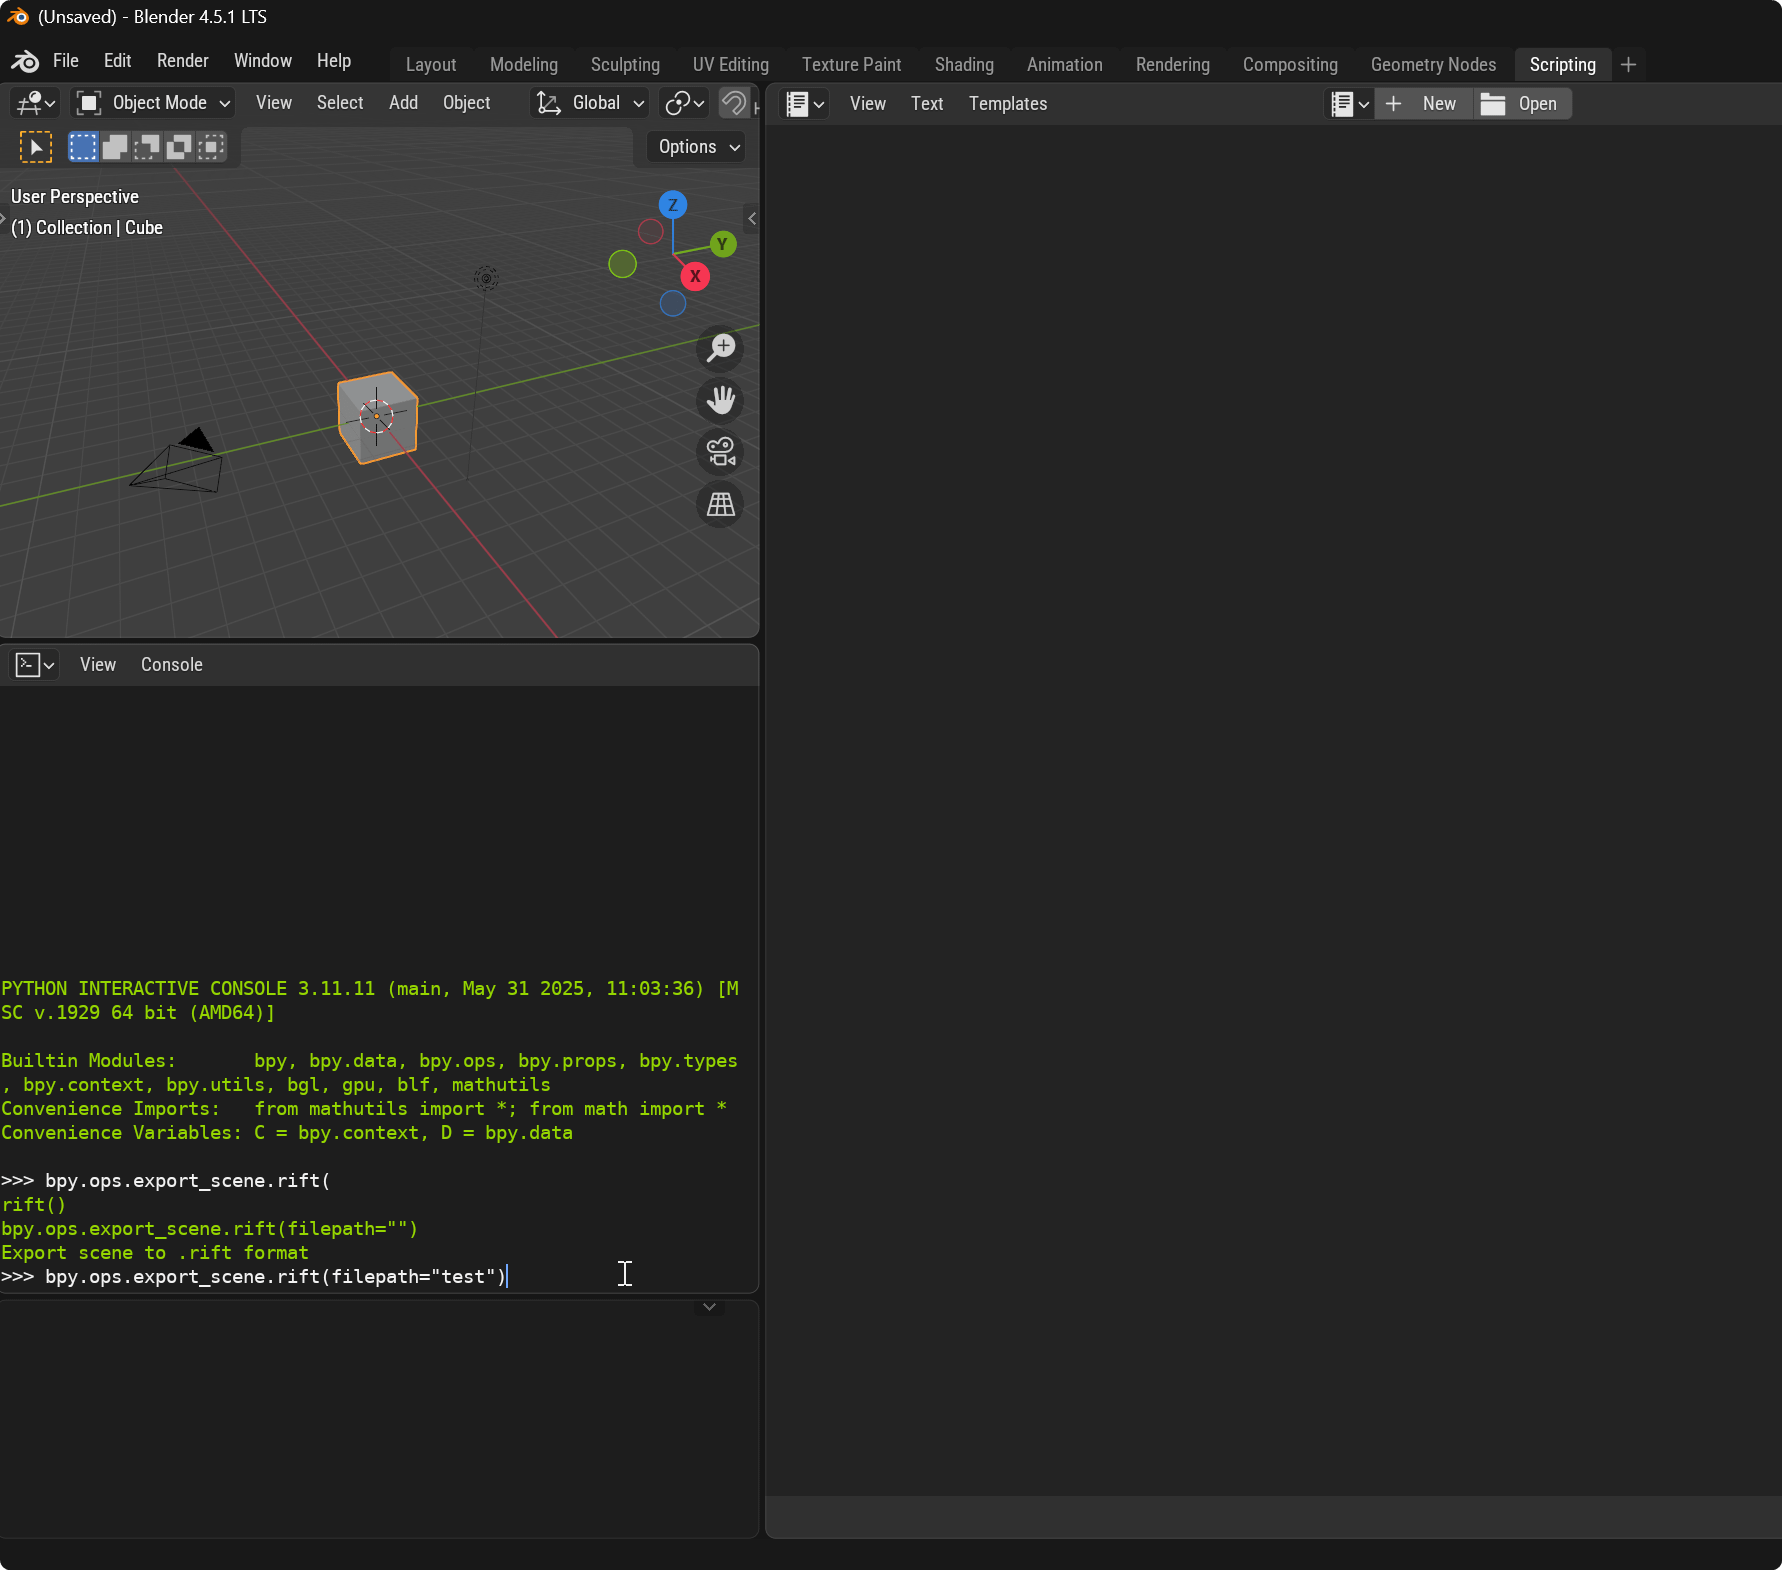
Iterating over all objects
To extend the hello exporter program, the following snippet loops through all the scene objects and prints their name:
static void rift_exporter_main (bContext *C, const char *filepath) {

    printf("We are in! \n");

    Scene *scene         = CTX_data_scene(C);
    Main *bmain          = CTX_data_main(C);
    Depsgraph *depsgraph = CTX_data_ensure_evaluated_depsgraph(C);

    LISTBASE_FOREACH(Object *, obj, &bmain->objects) {

        // In blender almost every name member has a 2 letter prefix, so we skip it
        char *name = obj->id.name + 2;
        printf("Object name: %s \n", name);
    }
}
Now it’s time to draw the rest of the owl :)
No, I’m just kidding. I will outline the exporter logic and note what needs to be done in order. Then I would provide detailed explanations and code snippets for each step.
Overall structure logic:
Loop through all materials, process them, and export texture data.
Loop through all objects, process meshes.
Save data to disk
Object processing logic:
Copy translation, rotation, scale, and model matrices
Process custom properties
Process mesh data
Get the mesh data (More involved than you’d think)
Triangulate the mesh if needed
Retrieve UVs, tangents, vertices, and normals
Copy vertices and indices
Material processing logic:
Get custom material data
Loop through the node graph
Get base color
Find the diffuse map and normal map textures
Export the textures if needed
Getting local matrix
The following snippet gets the local model matrix and the translation, rotation (in quaternions), and scale for an object. Unless your target engine mirrors Blender’s coordinate system conventions, you also need to convert them to your engine conventions.
float local_mat[4][4];
copy_m4_m4(local_mat, obj->object_to_world().ptr());

if (obj->parent) {
    float parent_inv[4][4];
    invert_m4_m4(parent_inv, obj->parent->object_to_world().ptr());
    mul_m4_m4m4(local_mat, parent_inv, obj->object_to_world().ptr());
}

float translation[3], rotation[3][3], scale[3];
mat4_to_loc_rot_size(translation, rotation, scale, local_mat);
float quat[4];
mat3_to_quat(quat, rotation);
normalize_qt(quat);
Getting mesh data
Getting the mesh data is a bit tricky. I also wanted to make sure that the live editing works when I’m in vertex editing, sculpting, or texture paining mode. You’ll notice that I show this in the demo video. But Blender comes with a whole set of quirks. For example if the object is in edit mode, and it has modifiers, then the get_evaluated_mesh function returns garbage data. Very cool! Well anyway, I suffered so you don’t have to! The following snippet of code returns to you the correct mesh data with all the modifiers applied. As the saying goes, it just works!™
if (obj->type == OB_MESH) {

    Object *obj_eval = DEG_get_evaluated(depsgraph, obj);
    Mesh *mesh = BKE_object_get_evaluated_mesh(obj_eval);
    if (mesh) {
        BKE_mesh_wrapper_ensure_mdata(mesh);
    }

    if (mesh && mesh->verts_num) {

        // Rest of mesh processing code
        // ...
        // ...
        // ...
    }
}
Triangulation
Despite Blender allowing you to author meshes with polygonal faces, game engines work with triangles, and we need to ensure that all our mesh faces are composed of triangles. Blender provides a function that automatically triangulates a mesh for us. Additionally, if you want to calculate/retrieve tangent data (which you’ll need if you do normal or parallax mapping), you also need to ensure that the mesh is triangulated. However, this function is quite expensive to run so you can save time by checking if the mesh needs to be triangulated in the first place and only doing it if it’s required.
bool needs_tri = false;
OffsetIndices <int> faces = mesh->faces();
for (int i : faces.index_range()) {
    if (faces[i].size() != 3) {
        needs_tri = true;
        break;
    }
}

if (needs_tri) {
    BMeshCreateParams bm_create_params = {false};
    BMeshFromMeshParams bm_convert_params = {};
    bm_convert_params.calc_face_normal = true;
    bm_convert_params.calc_vert_normal = true;

    BMesh *bmesh = BKE_mesh_to_bmesh_ex(mesh, &bm_create_params, &bm_convert_params);

    BM_mesh_triangulate(bmesh, MOD_TRIANGULATE_NGON_BEAUTY, MOD_TRIANGULATE_QUAD_SHORTEDGE, 4, false, nullptr, nullptr, nullptr);
    Mesh *triangulated = BKE_mesh_from_bmesh_for_eval_nomain(bmesh, nullptr, mesh);
    BM_mesh_free(bmesh);
    mesh = triangulated;
}
At the end of your mesh processing code, you need to free the triangulated mesh, otherwise you will leak memory like there is no tomorrow.
if (needs_tri) {
    BKE_id_free(NULL, mesh);
}
Getting UV data
The following snippet retrieves uv data from a mesh. It also creates an empty UV layer in the case no UV layers exist. Blender by default creates a UV layer for all meshes, but there are certain edge cases where there would be none. For example if you add a remesh modifier to an object, the uv data vanishes and you need to manually create one, which you cannot do unless you apply the modifier. So handling this programmatically is preferable to not disrupt your workflow.
char uv_name[MAX_CUSTOMDATA_LAYER_NAME] = {};
if (CustomData_number_of_layers(&mesh->corner_data, CD_PROP_FLOAT2) > 0) {
    int active_uv = CustomData_get_active_layer_index(&mesh->corner_data, CD_PROP_FLOAT2);
    BLI_strncpy(uv_name, mesh->corner_data.layers[active_uv].name, MAX_CUSTOMDATA_LAYER_NAME);
}
else {

    CustomData_add_layer_named(&mesh->corner_data, CD_PROP_FLOAT2, CD_SET_DEFAULT, mesh->corners_num, "DefaultUVMap");
    BLI_strncpy(uv_name, "DefaultUVMap", MAX_CUSTOMDATA_LAYER_NAME);
}

float (* uv_layer)[2] = (float (*)[2]) CustomData_get_layer_named(&mesh->corner_data, CD_PROP_FLOAT2, "DefaultUVMap");
if (!uv_layer) {
    uv_layer = (float (*)[2]) CustomData_get_layer(&mesh->corner_data, CD_PROP_FLOAT2);
}
Getting tangent data
float(*loop_tangents)[4];

if (CustomData_has_layer(&mesh->corner_data, CD_MLOOPTANGENT)) {
    loop_tangents = (float(*)[4]) CustomData_get_layer_for_write(&mesh->corner_data, CD_MLOOPTANGENT, mesh->corners_num);
    memset(loop_tangents, 0, sizeof(float[4]) * mesh->corners_num);
}
else {
    loop_tangents = (float(*)[4]) (CustomData_add_layer(&mesh->corner_data, CD_MLOOPTANGENT, CD_SET_DEFAULT, mesh->corners_num));
    CustomData_set_layer_flag(&mesh->corner_data, CD_MLOOPTANGENT, CD_FLAG_TEMPORARY);
}
BKE_mesh_calc_loop_tangent_single(mesh, uv_name, loop_tangents, nullptr);
Getting vertices, normals, and triangle data
The following snippet shows where the important vertex, normal, and triangle data are. I won’t cover this part in detail, since it’s case specific. But check the end of the article for a surprise which contains more useful information on this part.
Span <float3> vert_positions      = mesh->vert_positions();
Span <int>    corner_verts        = mesh->corner_verts();
Span <float3> corner_normals      = mesh->corner_normals();
Span <int3>   corner_tris         = mesh->corner_tris();
const int *   corner_tri_faces    = mesh->corner_tri_faces().data();
bke::AttributeAccessor attributes = mesh->attributes();
VArray <int> material_indices     = *attributes.lookup_or_default <int> ("material_index", bke::AttrDomain::Face, 0);
Iterating through Blender materials
You can separately iterate through blender materials without needing to loop through the objects. Since it’s very likely you’ll have a few materials that are shared between a lot of meshes, you’ll save a lot of time by iterating through the materials once, instead of iterating through them per mesh.
LISTBASE_FOREACH(Material *, material, &bmain->materials) {

    char *material_name = material->id.name + 2;
    printf("Material: %s", material_name);
}
Finding base color value of a material
The following snippet gets the base color value from the principled bsdf node which is the default node type when you create a material:
if (material->use_nodes && material->nodetree) {

    float color[3];

    LISTBASE_FOREACH(bNode *, node, &material->nodetree->nodes) {
        if (node->type_legacy == SH_NODE_BSDF_PRINCIPLED) {
            LISTBASE_FOREACH(bNodeSocket *, input, &node->inputs) {
                if (STREQ(input->name, "Base Color")) {
                    bNodeSocketValueRGBA *color_val = (bNodeSocketValueRGBA *) input->default_value;
                    if (color_val) {
                        color[0] = color_val->value[0];
                        color[1] = color_val->value[1];
                        color[2] = color_val->value[2];
                    }
                    break;
                }
            }
            break;
        }
    }
}
Finding material textures and determining their type
LISTBASE_FOREACH(bNode*, node, &material->nodetree->nodes) {
    if (node->type_legacy == SH_NODE_TEX_IMAGE) {
        Image *image = (Image *) node->id;
        if (!image) continue;

        bool normal_map = false;
        LISTBASE_FOREACH(bNodeLink*, link, &material->nodetree->links) {
            if (link->fromnode == node && link->tonode->type_legacy == SH_NODE_BSDF_PRINCIPLED) {
                if (STREQ(link->tosock->name, "Normal")) {
                    normal_map = true;
                    break;
                }
            }
        }
    }
}
Finding the path for image files
Since you want to export the images to your game engine, you most likely need to know the path to the image files. There are 2 cases. Either you have imported a texture from a file which in that case, the filepath can be retrieved, or the image has no file associated with it, likely because it was made in blender itself. In that case, the following snippet retrieves the image name:
// Get the path for the current blend file
char blend_file_dir[FILE_MAX] = {};
if (bmain->filepath[0]) {
    BLI_path_split_dir_part(bmain->filepath, blend_file_dir, FILE_MAX);
}

char abs_path[FILE_MAX] = {};

if (image->filepath[0]) {

    if (BLI_path_is_rel(image->filepath)) {
        BLI_path_join(abs_path, FILE_MAX, blend_file_dir, image->filepath + 2);
    }
    else {
        BLI_strncpy(abs_path, image->filepath, FILE_MAX);
    }
}
else {
    BLI_strncpy(abs_path, image->id.name + 2, FILE_MAX);
}
Exporting textures
A super nice thing about blender is that it supports various image formats, even .PSD files. And it’s super handy to be able to use those files when making levels. However, my game engine only supports loading in PNG images. Thankfully, Blender provides functions to convert to and from various file formats. The following snippet converts/exports images to PNG.
ImageSaveOptions opts;
BKE_image_save_options_init(&opts, bmain, scene, image, NULL, false, true);
opts.im_format.imtype = R_IMF_IMTYPE_PNG;
opts.im_format.compress = 0;
opts.im_format.depth = R_IMF_CHAN_DEPTH_8;
BLI_strncpy(opts.filepath, dest, sizeof(opts.filepath));

BKE_image_save(NULL, bmain, image, NULL, &opts);
BKE_image_save_options_free(&opts);
Important note:
If you run the snippet above as is, the exported image will have a subtly messed up color profile and will look different compared to the reference image.You have to add the following line at the top of your
exporter_mainfunction to make blender not mess up the exported image color profile.STRNCPY(scene->view_settings.view_transform, “Standard”);
R E A S O N A B L E.
Moving on … the image exporting process is quite slow! In my case it was by the far the slowest part of the whole export process. With some tricks, you can speed this process up. If your engine supports the same texture formats that you use in Blender and this is not a concern for you, then you don’t need to worry. You can just copy the image from the abs_path to your texture folder destination, and boom, you’re done!
Despite being in the blender source code, I try to avoid blender functions/interfaces as much as possible, and try to manually do the work, since I don’t know what the blender functions do, and it’s very likely they will be slower than just doing the work.
With that said, it’s time to include windows.h in blender. Yes you read that correctly!
#define WIN32_LEAN_AND_MEAN
#define NOMINMAX
#include <windows.h>
The headers provide us with the CopyFile api which I heavily suggest using over Blender’s provided file copy function. Blender calls CopyFile under the hood anyway. We need the windows headers later on for creating threads as well, but we’ll put that lotion in the basket in the optimizing section.
From what I gather, CopyFile is weird, and can behave very differently based on Windows version, obscure windows settings related to disk cache, and disk storage type. I would also recommend calling it only if necessary.
In my case I use meow hash (can highly recommend) to compare the source and destination files and only call CopyFile in the case where the files are different. In my setup, I do notice a notable speed improvement doing this than just repeatedly calling CopyFile. This surprised me as I would’ve assumed that windows has a mechanism under the hood to avoid redundant file copies.
All of that was for the case where you are copying the image and don’t need to convert the image to another format. It’s even more important to only export if needed, since it takes much more time than just copying the image. The following snippet shows how you can avoid unnecessary image export operations:
bool save_image = false;
u64 source_time = getFileLastWriteTime(source);
u64 dest_time   = getFileLastWriteTime(dest);
if      (!BLI_exists(dest))         save_image = true;
else if (source_time > dest_time)   save_image = true;
else if (BKE_image_is_dirty(image)) save_image = true;

if (save_image) {

    // Export the image file
    // ...
}
Since the source and destination files are different, we can use the file timestamp to detect changes. Thankfully windows makes it quite easy for us to get the get the file modification date:
u64 getFileLastWriteTime (char *filename) {

    FILETIME                    time    = {0};
    u64                         result  = 0;
    WIN32_FILE_ATTRIBUTE_DATA   data;

    if (GetFileAttributesExA(filename, GetFileExInfoStandard, &data)) {

        time = data.ftLastWriteTime;
        result = ((u64)time.dwHighDateTime << 32) | time.dwLowDateTime;
    }

    return result;
}
The function BKE_image_is_dirty is quite useful as well, and it’s used to detect if a texture was modified directly in Blender in the texture painting mode. You’ll notice that I demo it in the video as well.
Finally, you can save yourself a lot of work by checking if you have already exported/copied an image, and not doing it multiple times, for example in the case where multiple materials share a common texture.
Getting custom data
In Blender, you can add custom data to objects, and materials through python. This is super good because then you can have your entity properties be all available to edit right from Blender UI.
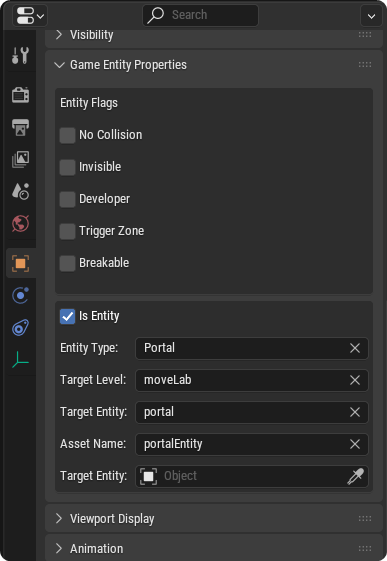
Here is how you can retrieve the data:
void get_custom_data (const ID* id, const char* name) {

    if (id->properties) {
        IDProperty *prop = IDP_GetPropertyFromGroup(id->properties, name);
        if (prop) {

            // Float case:
            float foo = IDP_Float(prop);

            // Float3/float array case:
            if (prop->type == IDP_ARRAY && prop->subtype == IDP_FLOAT) {
                float *foo = (float *) IDP_Array(prop);
            }

            // Int case:
            int foo = IDP_Int(prop);

            // Bool case:
            bool foo = IDP_Bool(prop);

            // String case:
            char *foo = IDP_String(prop);

            // Node/object case:
            Object *foo = NULL;
            if (prop->type == IDP_ID) {
                ID *target_id = (ID *) prop->data.pointer;
                if (target_id && target_id->name[0]) {
                    foo = (Object *) target_id;
                }
            }
        }
    }
}
The id in this case is the id pointer accessible from the type you are trying to access the custom properties from. For example an Object or Material, and name is the custom property name that you defined on the python side.
Object *object = ...
Material *material = ...

ID *id = object->id;
// or
ID *id = material->id;
Important Note:
If your custom property value is set to the default value in the Blender UI, theIDP_…set of functions do not retrieve anything. You would need to mirror the default initial values in the C code, or make sure that your custom properties all have 0 as the default value.
Retrieving custom data for an array of objects (Collection Properties) is different than the above. An example of a case like this is a button that can target multiple objects like so:
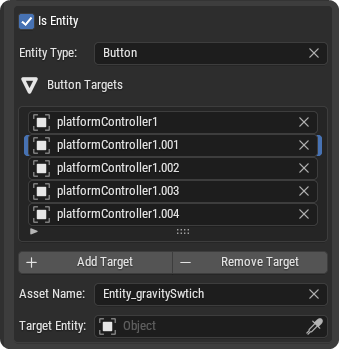
PropertyRNA *collection_prop;
PropertyRNA *obj_prop;
CollectionPropertyIterator iter;

PointerRNA obj_ptr = RNA_id_pointer_create(&obj->id);
collection_prop = RNA_struct_find_property(&obj_ptr, "button_target_entities"); // Name of the property

if (collection_prop) {
    RNA_PROP_BEGIN(&obj_ptr, itemptr, collection_prop) {

        obj_prop = RNA_struct_find_property(&itemptr, "obj");
        if (obj_prop) {

            PointerRNA target_ptr = RNA_property_pointer_get(&itemptr, obj_prop);
            Object *target_obj = (Object *) target_ptr.data;
            if (target_obj) {

                // ...
                // ...
                // ...
            }
        }
    } RNA_PROP_END;
}
Serializing
I won’t cover the serializing process in detail since at this point you really don’t have anything to worry with Blender, and just need to send the data to your game engine, and it would be super specific to your game engine anyway. But my tip is to serialize the data directly to the format that your engine operates on. So on your engine side, your deserialization code would look extremely simple and would essentially be one big memcpy to copy the data from the disk to memory. Also, since it’s just C code, your serializer and deserializer can share code and always remain in sync.
With that said, if you are interested in learning about a very neat and performant way of implementing a backwards compatible serialization/deserialization system, I can highly recommend the following article:
Python … sigh
Unfortunately, not all of the exporter parts can remain in C, and some parts have to be written in Python. The UI still has to be written in Python and also the exporter would get invoked from Python. My experience with Python has been quite miserable, but the silver lining is that our setup makes developing the python part just a little bit nicer by the fact that the build script also updates the python scripts without needing to manually load and unload the addon in Blender settings.
I won’t dive into the python parts in this article, mainly because this article is already super long, and there are a lot of resources available on the python scripting side of things.
To load the python addon, create a python script in the /scripts/startup/ folder, and compile with ninja install. This will copy the startup scripts to the blender binary folder, and blender will happily load and register our plugin on startup. This command also takes a longer time to finish the first time you run it.
I would highlight one part of the python addon that is useful for continuous exporting and hot-reloading. You can register a callback that gets triggered when something in the scene changes.
# Callback
def depsgraph_update_handler(scene, depsgraph):
    global scene_updated

    if depsgraph.id_type_updated(’OBJECT’) or depsgraph.id_type_updated(’MESH’) or depsgraph.id_type_updated(’MATERIAL’):
        scene_updated = True

# Register the callback
bpy.app.handlers.depsgraph_update_post.append(depsgraph_update_handler)
I also recommend to throttle the export rate, in my case the export is throttled to 16ms intervals (60 hz).
Optimization
The key to improving speed is to keep interaction with Blender’s provided API to a minimum, since you can easily write routines that outperform Blender’s.
With that said, you can maximize speed through these strategies:
Custom memory allocation through arenas.
Lockless multithreading.
And a mystery sauce that I’ll cover later.
If you want to learn more about these topics, check the Appendix, where I provide links to recommended learning material.
Before moving on to the optimization specifics, it’s very important to have profiling data. Having a reliable profiler is extremely important to understand the application.
With that said, I can highly recommend Superluminal Profiler, which is what I used as well. The best part is that since it’s a sampling profiler, and you don’t need to make any modifications to the code. Simply launch the compiled blender executable through Superluminal and have profiler information available!
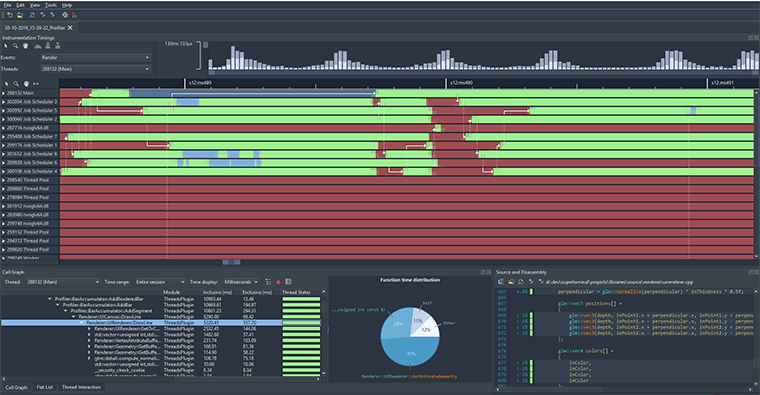
While you can obviously write your own instrumentation based profiler, I still would recommend a sampling profiler like Superluminal, it will save a lot of time, and can give you data on parts of the code that you haven’t marked up. Considering that this is a hugely complicated codebase with atrocious compile times, the benefits of a Sampling profiler really shine through!
With that out of way, here are the major factors to keep in mind to make the code run fast:
Arenas!
Using arenas for memory allocation and de-allocation. Using a "linear arena" makes allocating memory and freeing it not just very hasslefree, but extremely fast!
Avoid the standard library!
I urge you to write your own array implementations, and use statically sized arrays where possible. Avoid using null-terminated strings. Avoid using the fopen, fwrite, … family of functions for file operations. Instead, use the Windows specific ones (CreateFileA, WriteFile, …) as they are much more performant and provide you with more options such as memory mapping a file.
Parallelize the operations!
Thankfully, the process of exporting, is as the saying goes … embarrassingly parallelizable™. You can setup a job system with worker threads, with each thread picking an object to process. The rough outline would look like this:
Gather all objects to process
Gather all texture operations to process (copy, or export)
Start all threads, with each thread having its own arena
Threads pick jobs and churn through the objects in parallel.
Serialize the data when all jobs are done
Extra Sauce:
When I profiled the code, it became apparent that the disk IO operations was the slowest part of the export process. And even though I’m on a fast SSD, it’s still slower than operating with data in memory.You can create a shared memory region between Blender and the game engine and serialize the data directly to the shared memory. This way, the exporter will run even faster by avoiding OS functions calls for disk IO.
You could also use memory mapped files for even faster disk IO operations.
I didn’t do either, because I had exceeded my performance goals. I originally set my target as 16ms and the final exporter exports my biggest level in 9ms so I was already very happy to take the win and go work on other parts of the game.
Changing the splash screen
Last but not least, this is obviously the most important modification, and if you don’t replace the splash screen with an epic picture, all bets are off and I cannot make any guarantees whether or not the exporter will work.
With that said, all you need to do is to modify the image file at blender/release/datafiles/splash.png and recompile. You might have to call ninja install for the splash screen to update.
Closing remarks
Writing this exporter has been extremely satisfying, especially since I wasn’t even sure it was possible when I started. It’s been incredible to see so many people recognize the value of this approach. Considering that the ultimate goal is to create great games in shorter time spans, I think that this approach will save you significant development time.
This article took a lot of time to write. I hope you found it useful. If you have more questions, feel free to reach out to me. And also if you find better ways of doing things than what I’ve shown here, I’d love to hear from you!
I would like to also thank the community members in the Blender Coders matrix chatroom where they helped me with questions.
I’m really looking forward to seeing your own exporters and engines, and I with that sai-
!!!! O M G !!!! What is this?
That’s right! I’m also sharing my exporter source code!
Despite some hesitation, I’ve decided to share my implementation since I think it can help a lot of you by seeing the whole picture view of what I’ve done, including the python bits.
Ultimately, I think sharing this knowledge is the right thing to do and I wouldn’t be anywhere without my kind predecessors who openly shared their hard-earned knowledge. This is my way of paying that kindness forward.
Thank you for taking the time to read this article.
-Taha
Appendix
Lockless multithreading learning resource:
Dennis Gustafsson’s talk at Better Software Conference explains lockless multithreading quite well.
Casey Muratori covers it in detail in the Handmade Hero series:
Arenas learning resource:
Bill Hall and Ryan Fleury have great written articles on memory arenas:
https://www.gingerbill.org/article/2019/02/08/memory-allocation-strategies-002/

(Timestamped clip) https://youtu.be/90vqCKEEj3s?si=eQ2KUCPpQzwbE6Xc&t=1623
https://youtu.be/G5VeATrOST4?si=KfPapWaM-j4HYC0k
That's pretty cool! I came to the same conclusion concerning blender as a level editor but i achieved hot reloading of my levels with a build/file watcher nob style, which obviously doesn't go as fast as this.
I haven't bitten this bullet yet. I'm still working with my bespoke editor, exporting obj from blender, opening in it, screaming all throughout the process.
I'm gonna have to do this at some point.